
Full corpus of 15,795 speech records from the Science, Technology, Information, Broadcasting and Communications Committee of the 22nd Korean National Assembly (2024). Standing committee meetings only.
Format
A data frame with 15,795 rows and 10 variables:
- assembly
Assembly number (22)
- date
Date of the committee meeting
- committee
Committee name in Korean
- speaker
Speaker label as it appears in the minutes (may include titles)
- role
Speaker role: "legislator", "chair", "minister", "vice_minister", "senior_bureaucrat", "agency_head", "witness", "expert_witness", "nominee", "minister_nominee", "testifier", "public_corp_head", "broadcasting", "committee_staff"
- speaker_name
Cleaned speaker name with titles removed
- member_id
Legislator identifier (MONA_CD, links to
legislators$member_id) for the 12,060 speeches by members of the Assembly.NAfor other speakers (ministers, witnesses, and the heads of other bodies).- speaker_id
Numeric speaker identifier used in the committee minutes, which versions up to 0.1.3 stored in
member_id.NAfor speakers who are not members of the Assembly.- speech_order
Order of the speech turn within the meeting
- speech
Full text of the speech in Korean
Details
This dataset contains the complete standing committee speech records
(no sampling) for the Science and ICT Committee of the 22nd assembly
(June-December 2024). Speeches shorter than 50 characters were excluded.
date and speech_order identify a speech, except on
2024-06-25, when two meetings were held and eight speech_order
values occur twice.
Up to version 0.1.3, member_id held the numeric speaker
identifier of the minutes, so it did not link to
legislators$member_id, and 48 speeches of 2024-08-14 appeared
twice under two speaker identifiers. Version 0.1.4 attaches the MONA_CD
through the member records of release 0.7.0 of the kna project and
drops the duplicates.
The role variable distinguishes legislators from government
officials, witnesses, and other participants. Filter to
role == "legislator" for MP speeches only, or compare how
legislators and ministers discuss the same agenda items.
This committee covers AI, telecommunications, broadcasting, space policy, and R&D governance, making it suitable for keyword analysis, topic modeling, and other text analysis exercises.
Examples
data(speeches)
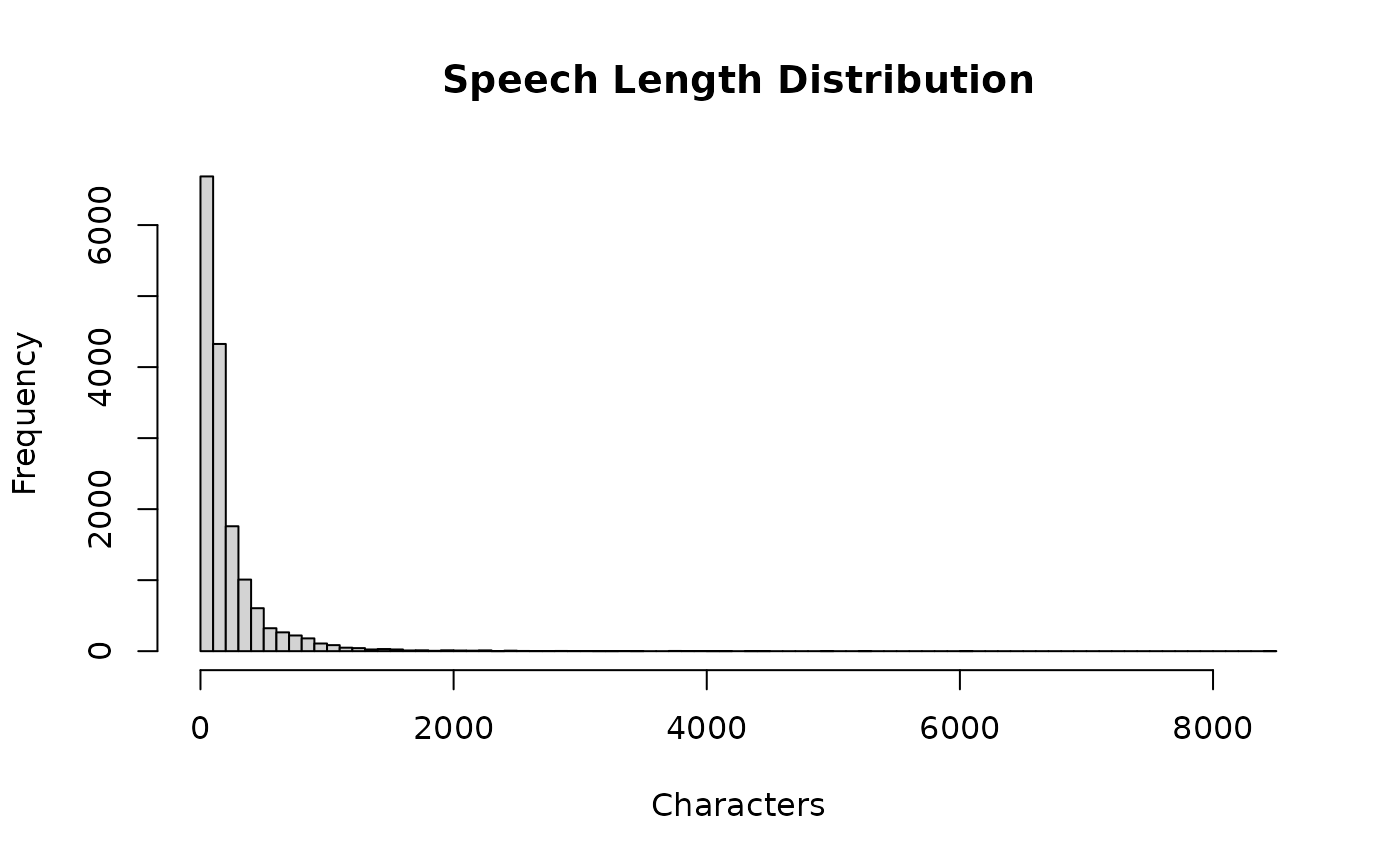
# Distribution of speech lengths
hist(nchar(speeches$speech), breaks = 100,
main = "Speech Length Distribution", xlab = "Characters")
 # Speaker roles
table(speeches$role)
#>
#> agency_head broadcasting chair committee_staff
#> 31 46 3821 27
#> expert_witness legislator minister minister_nominee
#> 720 9050 196 151
#> nominee public_corp_head senior_bureaucrat testifier
#> 349 187 62 77
#> vice_minister witness
#> 70 1008
# Most frequent legislator speakers
leg <- speeches[speeches$role == "legislator", ]
head(sort(table(leg$speaker_name), decreasing = TRUE), 10)
#>
#> 김현 노종면 최형두 이훈기 이정헌 한민수 황정아 김우영 조인철 이준석
#> 1105 826 717 630 576 527 512 503 491 384
# Simple keyword search (example: AI-related speeches)
ai <- speeches[grepl("AI", speeches$speech), ]
nrow(ai)
#> [1] 294